
Recipe content inside a food-tech platform doesn’t move from “published” to “done.” It moves through a pipeline: ingestion, normalization, content modeling, metadata and taxonomy, quality validation, transformation, distribution, and ongoing governance. Each stage determines whether a recipe can be searched, recommended, personalized, made shoppable, reused in a new product experience, or understood by AI systems.
For product, content, engineering, partnerships, and operations teams, that pipeline is the real content infrastructure. The visible recipe card is only one output. Behind it is a structured system of fields, rules, relationships, identifiers, and decisions that determines what the platform can do with the content next.
So content strategy in food tech can’t stop at publishing. If the underlying recipe data is inconsistent, incomplete, or trapped in presentation-specific formats, every new feature becomes harder to build. Search quality suffers. Recommendations become less reliable. Creator onboarding requires more manual cleanup. Commerce integrations need workarounds. AI experiences inherit the same gaps.
The practical question goes from “Do we have recipes?” to “Can our systems understand, trust, and use those recipes across the experiences we want to build?”
What happens to recipe content inside a platform?
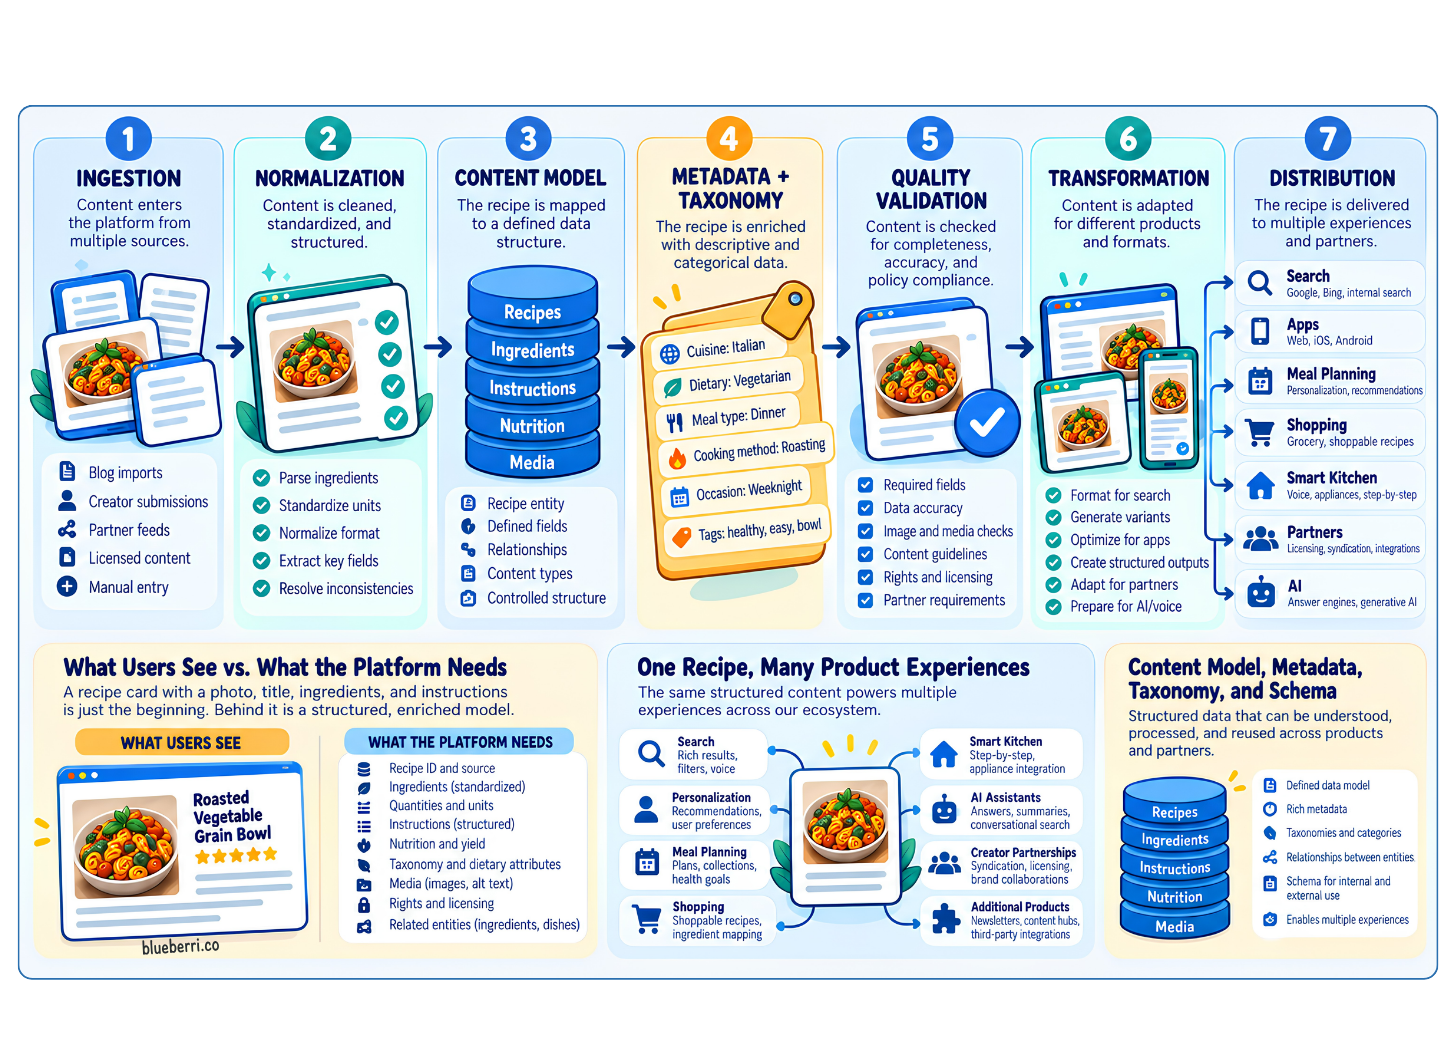
A recipe platform typically receives content from multiple sources: creator submissions, publisher feeds, licensed libraries, CMS exports, APIs, spreadsheets, partner integrations, or internal editorial teams. Those sources rarely arrive in exactly the same structure. One partner may send prep time as a number, another as free text. One source may separate ingredient quantity, unit, and ingredient name; another may provide a single ingredient string. Dietary labels may use different terms for the same concept.
Before that content can reliably power product experiences, the platform has to make those differences manageable. That usually means converting incoming content into a shared internal model, applying consistent metadata, validating required fields, and defining which values are accepted. From there, the same underlying recipe can be transformed for search, apps, meal planning, commerce, smart appliances, partner feeds, and AI-driven interfaces.
The more destinations a platform supports, the more important this shared structure becomes. Without it, teams end up creating one-off mappings for every feature and integration. That may work for the first launch. It becomes expensive when the content library, partner network, and product surface area grow.
Why recipe content becomes infrastructure, not just editorial copy
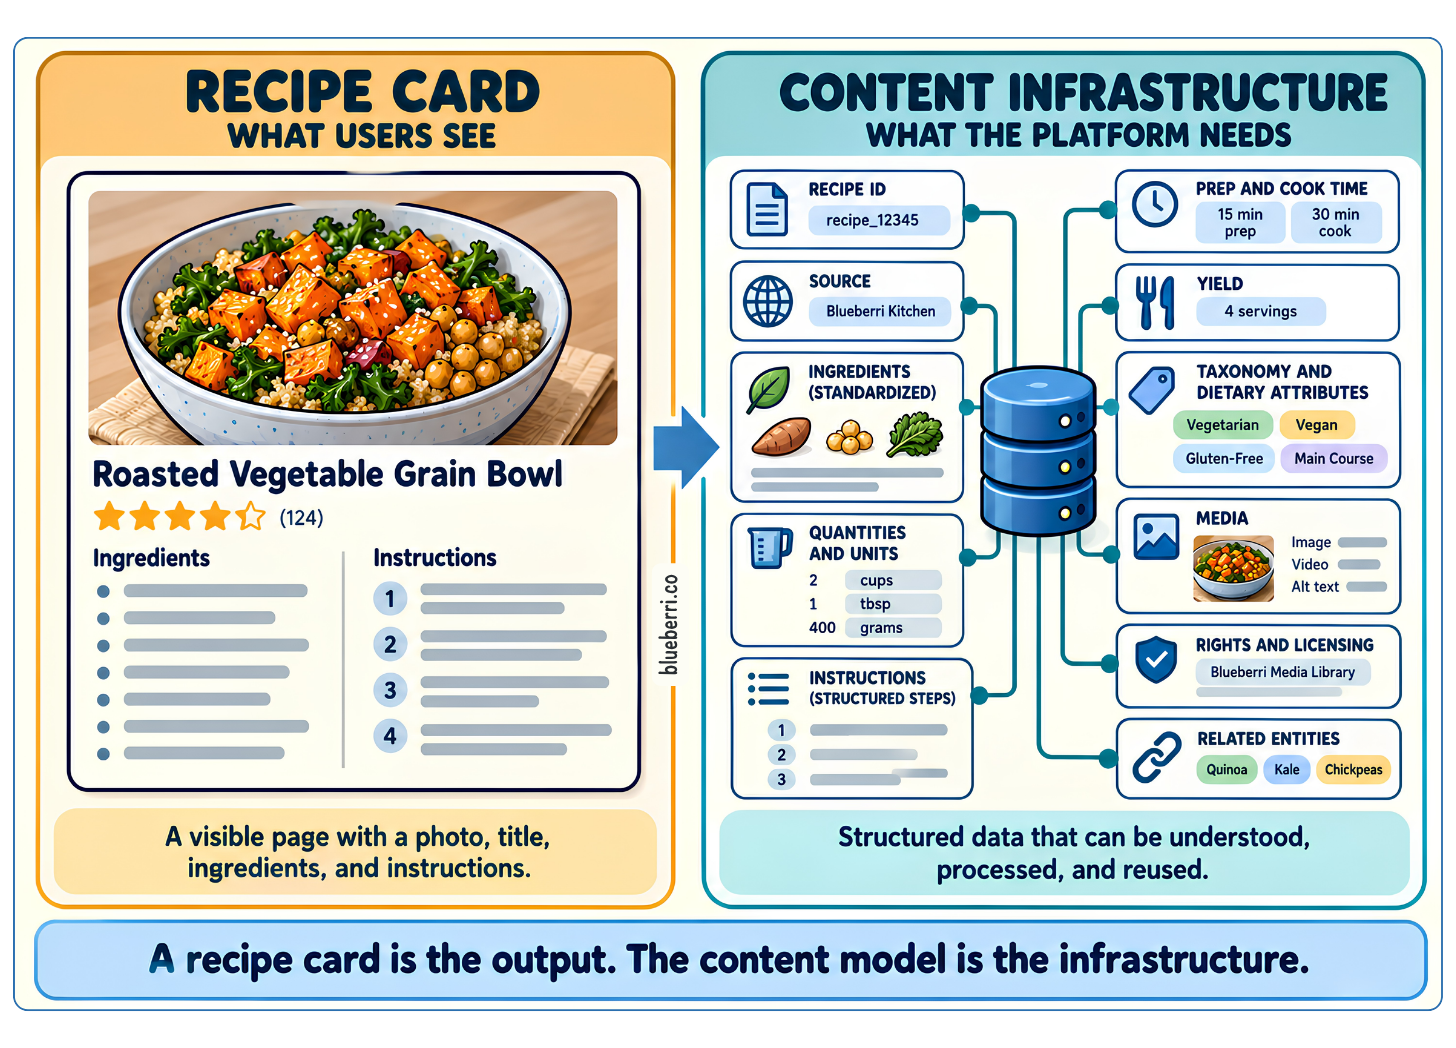
Food content usually enters a company through an editorial lens. The immediate questions are understandable: Is the recipe accurate? Is the photography strong? Does the introduction match the brand voice? Those questions still matter. But once recipes are expected to move through software systems, editorial quality is only one part of the job.
A platform also needs to know what each piece of information means, where it belongs, which values are allowed, and how one field relates to another. “30 minutes” must become a usable duration. “Vegetarian” must be distinguishable from “vegan.” “1 cup chopped walnuts” may need to be parsed differently depending on whether the product supports grocery matching, nutrition, scaling, substitutions, or unit conversion.
We’re experiencing the shift from content as a page to content as infrastructure. The page is an experience. The structured content underneath it is what allows the experience to change without rebuilding the content from scratch.
The seven stages of a recipe content pipeline
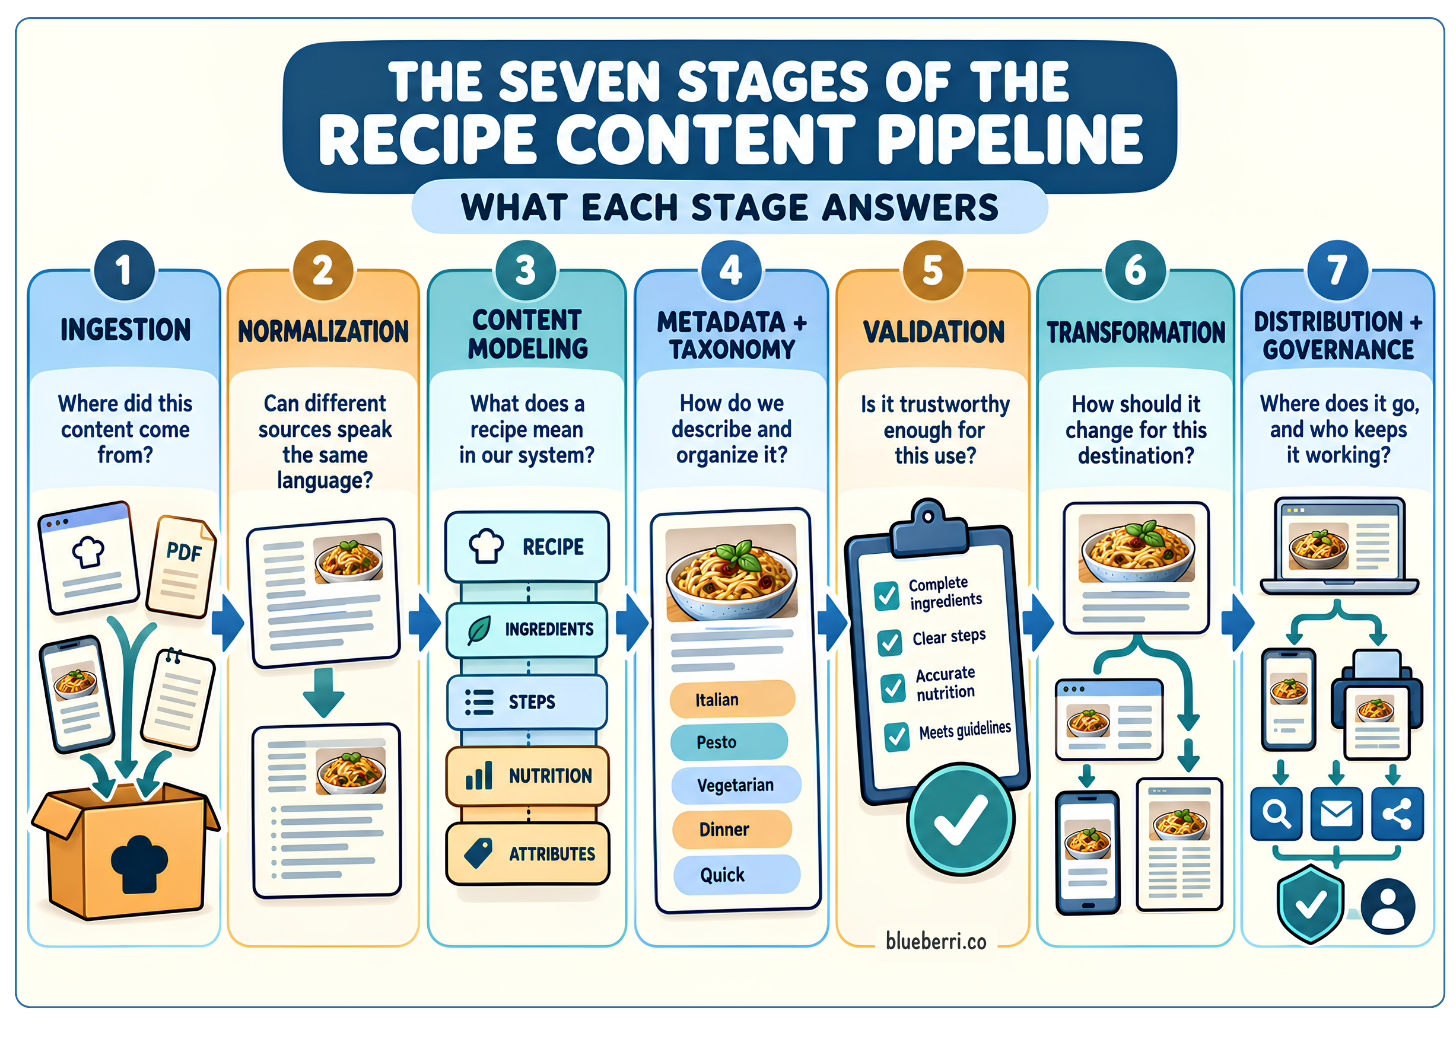
1. Ingestion: getting content into the system
Ingestion is the entry point. A platform receives recipe content through a defined channel and captures the source as faithfully as possible. The goal is not to “fix everything” immediately. The goal is to preserve enough source information that later processing can happen without losing context.
Strong ingestion workflows record source IDs, ownership or licensing information, timestamps, partner identifiers, source URLs when relevant, and the raw values received. Those details matter later for attribution, rights management, troubleshooting, reprocessing, and synchronization.
When ingestion is treated as a copy-and-paste task, teams can lose provenance. Months later, no one knows which partner supplied a value, whether the platform changed it, or which record should be updated when the original source changes.
2. Normalization: making different inputs comparable
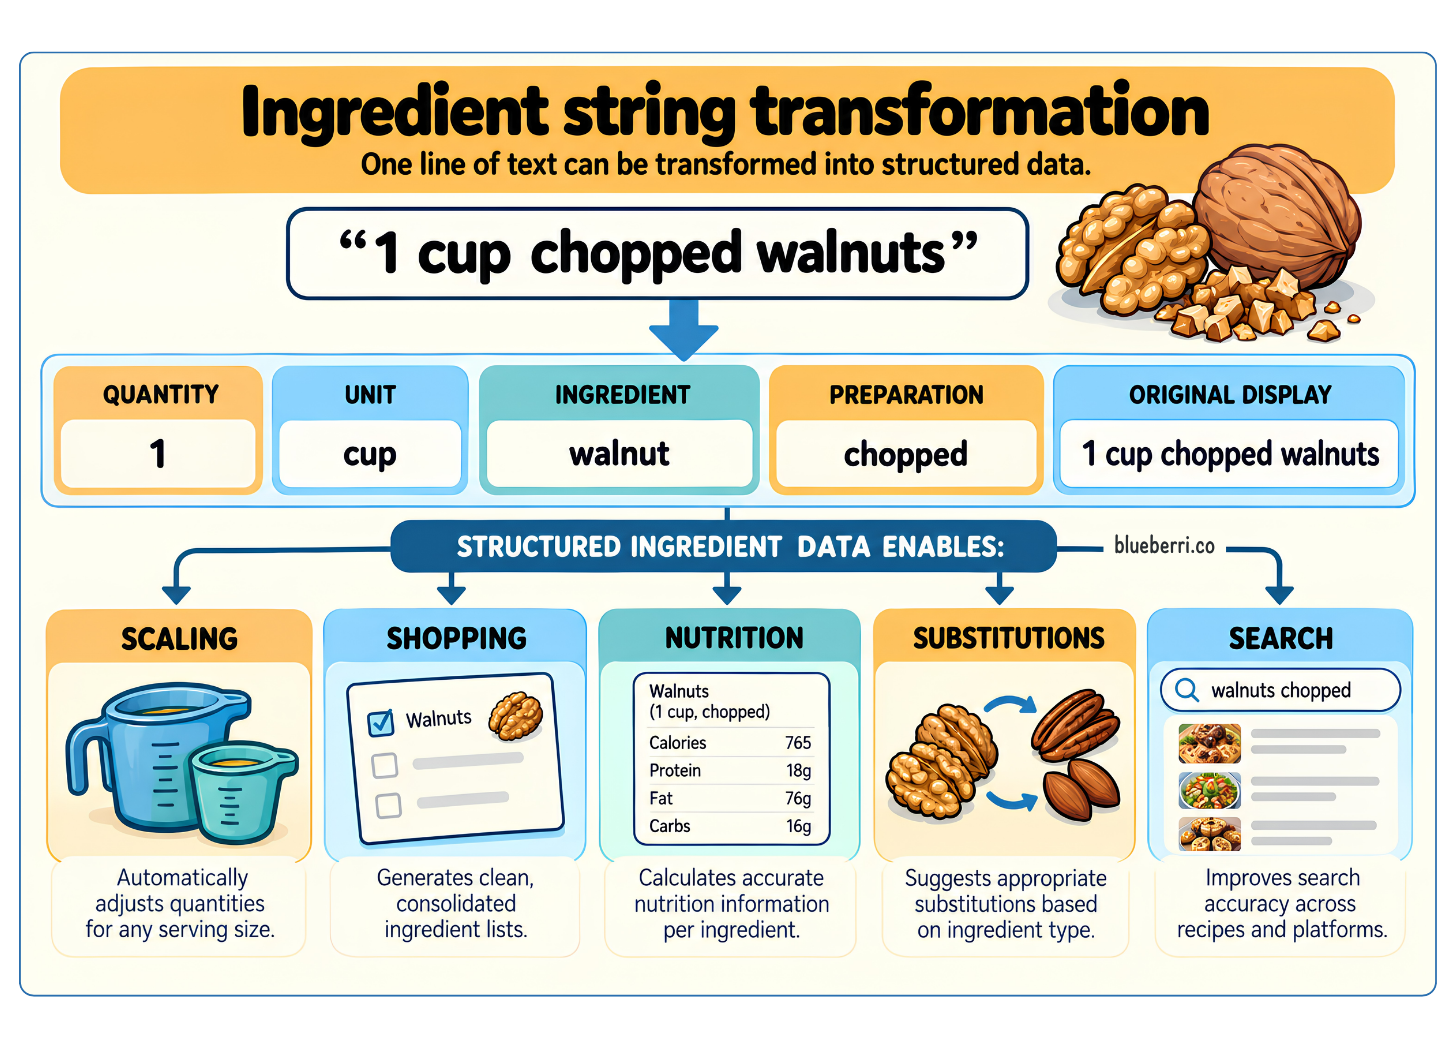
Normalization converts inconsistent source values into a shared representation. It is where “30 mins,” “0:30,” and “thirty minutes” may all become the same duration format. It is where pluralization, unit conventions, whitespace, capitalization, field order, and known aliases can be standardized.
Normalization isn’t the same as flattening. A platform shouldn’t erase meaningful distinctions just to make data look uniform. The goal is to create consistency where consistency enables the product, while preserving source detail when it carries meaning.
Ingredient data plays an essential role here. If an ingredient line exists only as a display string, it may be sufficient for a recipe page but insufficient for shopping, scaling, substitutions, nutrition, or inventory matching. A more structured representation can separate quantity, unit, ingredient, preparation state, and optional modifiers while still preserving the original line for display.
3. Content modeling: defining what a recipe is inside the product
A content model defines the entities, fields, relationships, and rules the platform needs. A recipe may include title, description, ingredients, instructions, timing, yield, images, video, author, cuisine, dietary attributes, techniques, equipment, collections, nutrition, source, rights, and commerce data. But not every platform needs the same model.
The right model starts with product requirements. A meal-planning app may care deeply about serving size, schedule, leftovers, and dietary preference. A grocery integration may prioritize ingredient identity, quantity, unit, and purchasability. A creator marketplace may need contributor identity, licensing terms, campaign associations, and usage rights in addition to the recipe itself.
A common mistake is allowing the CMS or recipe card plugin to define the content model by default. Those tools are implementation choices. The model should describe the business and product needs first, then be expressed in the systems that support them. For a deeper explanation, see Blueberri’s guide to content modeling, recipe schema, and taxonomy.
4. Taxonomy and metadata: giving content shared meaning
Metadata describes content. Taxonomy organizes that metadata into controlled concepts and relationships. Together, they help the platform answer questions such as: Is this recipe a breakfast or dessert? Which cuisine does it belong to? Is it gluten-free, vegetarian, or dairy-free? Which cooking methods does it use? Is it appropriate for a 30-minute meal filter?
Without governance, these values multiply quickly. “Air fryer,” “air-fryer,” “Air Fryer Recipes,” and “airfried” may all appear as separate tags even when the product intends them to represent one concept. The problem is not cosmetic. Fragmented terms make filters unreliable, analytics harder to interpret, search less predictable, and AI retrieval noisier.
Taxonomy work creates shared language across content, product, data, and engineering. When those teams use the same definitions, the platform can build features against stable concepts instead of guessing what freeform labels mean. Explore the foundations in Metadata 101 for recipe data.
5. Quality validation: deciding what “good enough to use” means
Content validation checks whether a recipe meets the requirements for a specific use. That’s different from asking whether a recipe is generally “complete.” A record may be good enough to display in a simple web page but not good enough to support grocery matching or personalized recommendations.
Validation can include required fields, accepted formats, allowed values, relationship checks, duplicate detection, image requirements, ingredient parsing confidence, instruction completeness, licensing status, and business rules. The most useful validation is tied to downstream consequences. A missing yield field is not just a blank cell; it may break scaling. A missing dietary attribute may exclude a recipe from personalization. A missing source identifier may make partner updates difficult to reconcile.
Platforms should define quality gates by use case. That makes the conversation more actionable than a single vague standard of “content quality.”
6. Transformation: adapting one source to multiple experiences
Once the internal content is reliable, transformation adapts it for a destination without changing the source of truth. A mobile app may need shorter display labels. A search index may need normalized text and synonyms. A partner API may need a different field structure. A commerce workflow may need ingredient records mapped to purchasable items. An AI assistant may need concise, retrievable steps plus context about equipment, time, and substitutions.
Transformation is where structured content creates leverage. Teams can change the output without manually rewriting the recipe for every channel. That doesn’t mean every destination receives identical content. It means the differences are intentional, governed, and generated from a shared foundation.
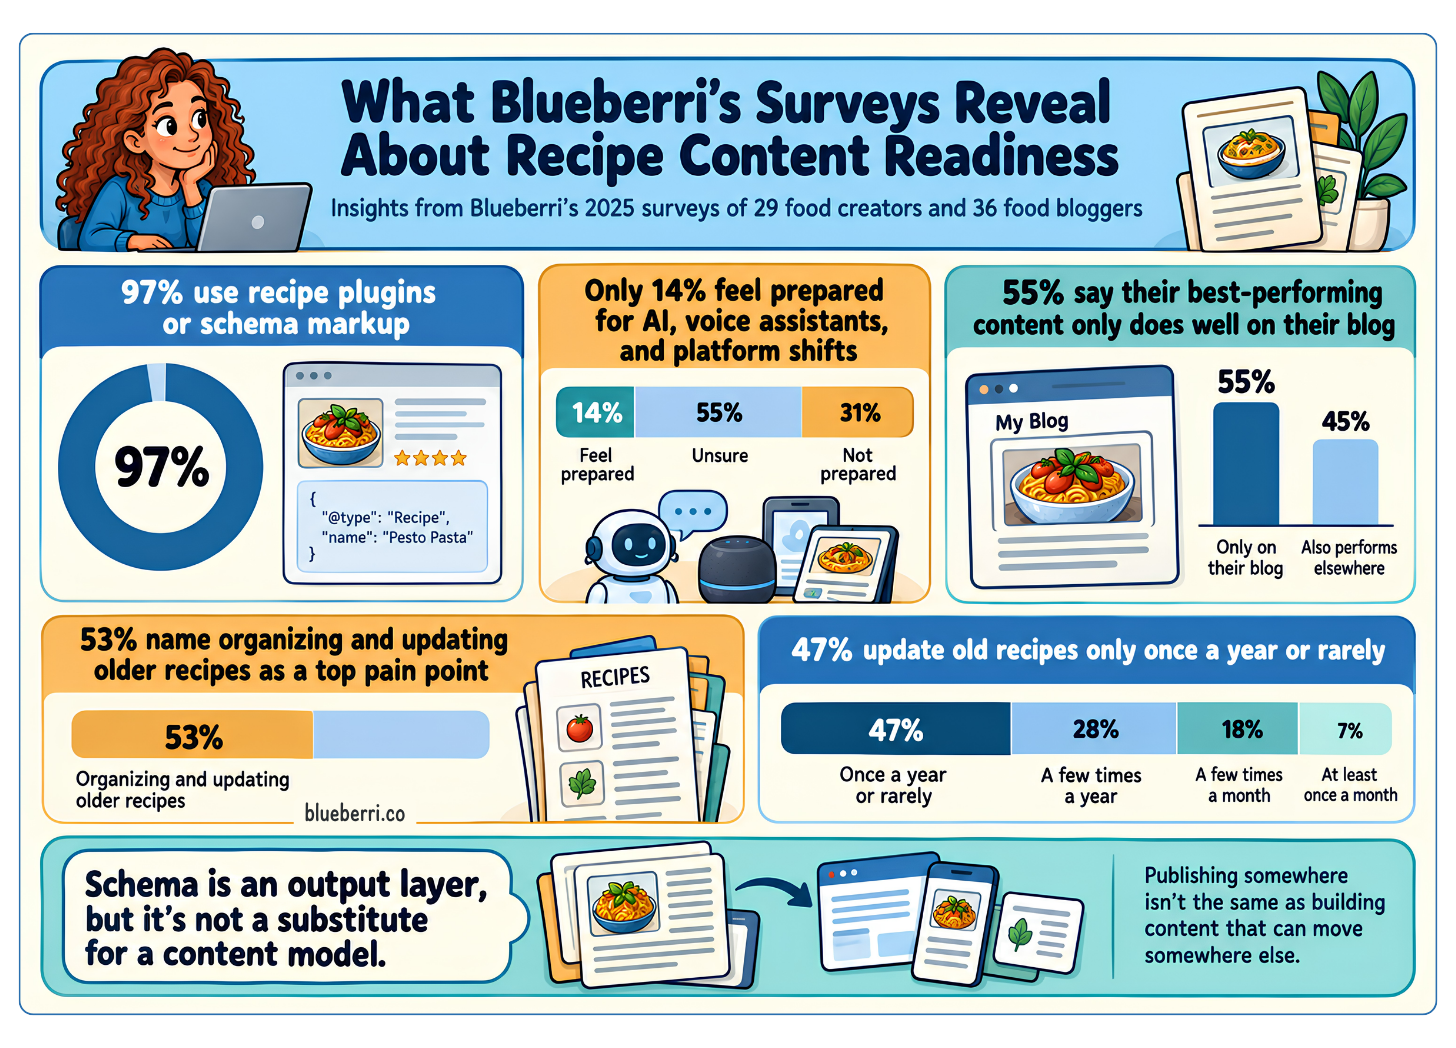
In Blueberri’s 2025 survey of 29 food creators, 55% said their best-performing content only does well on their blog rather than across multiple platforms. Publishing somewhere isn’t the same as building content that can move somewhere else.
7. Distribution and governance: keeping content useful after launch
Distribution sends the transformed content into the places where it creates value: websites, apps, search systems, recommendation engines, shopping experiences, partner feeds, smart devices, internal tools, and AI interfaces.
But distribution isn’t the end of the lifecycle. Recipes change. Partners update their feeds. Products add new fields. Taxonomies evolve. Rights expire. Search behavior changes. New AI experiences require context that an older model never captured.
That’s why content governance belongs in the pipeline. Teams need ownership for definitions, change management, deprecation, source synchronization, quality monitoring, and the rules for introducing new metadata. Otherwise, the content model slowly accumulates exceptions until the platform is difficult to maintain.
In a separate Blueberri survey of 36 food bloggers, 53% named organizing and updating older recipes as one of their top pain points, and 47% said they update old recipes only once a year or rarely. Governance isn’t a one-time cleanup. It’s the work that keeps content useful after launch.
What data does a recipe platform actually need?
There’s no universal recipe model, but most platforms need a reliable core before they can support more advanced experiences. At minimum, teams should be able to identify and manage the recipe, its ingredients, instructions, timing, yield, media, source, and key descriptive metadata.
A practical core often includes: recipe ID; title and description; ingredient groups and ingredient lines; instruction groups and steps; prep, cook, and total time; yield or servings; author or source; images and video; cuisine; course or meal type; dietary attributes; cooking methods; equipment; taxonomy terms; nutrition when supported; rights or licensing information; and timestamps or version information.
For AI, personalization, commerce, and cross-platform distribution, the important question isn’t how many fields the model contains. It’s whether the fields are defined consistently enough to be trusted. Ten well-governed fields can be more useful than fifty ambiguous ones.
Recipe schema, content models, metadata, and taxonomy are not the same thing
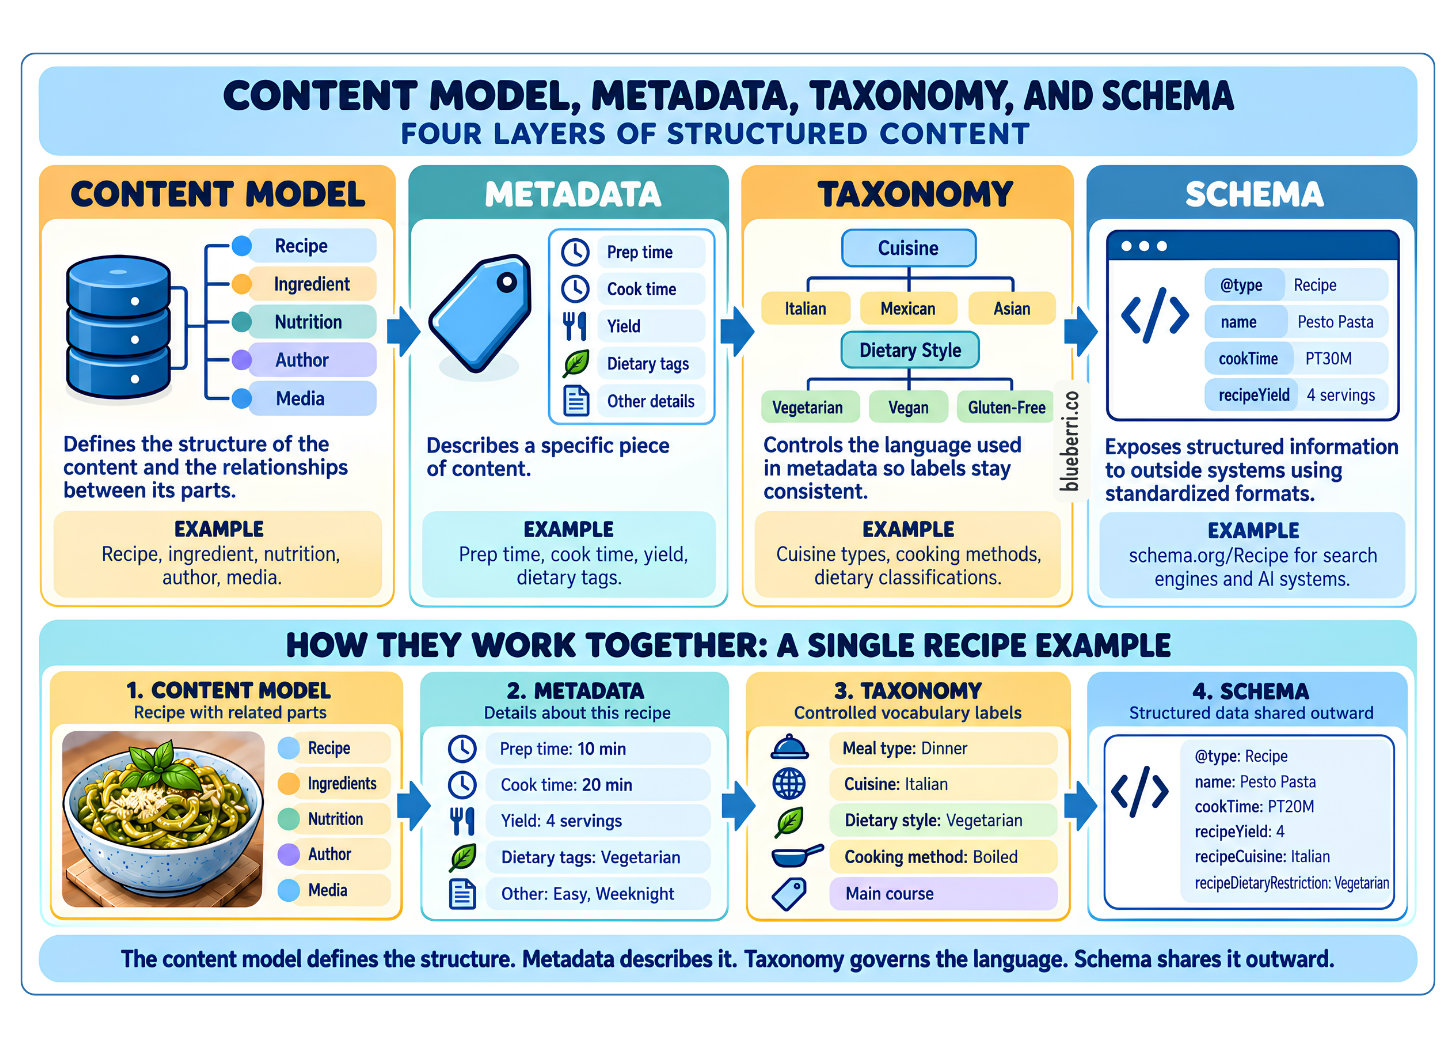
Teams often use these terms interchangeably, which creates confusion.
A content model defines the internal structure of the content and includes the entities, fields, relationships, and constraints the system uses. Metadata describes a specific piece of content, such as cuisine, method, dietary attributes, or source. A taxonomy defines controlled concepts and relationships used to keep that metadata consistent. Recipe schema is a standardized way to expose recipe information so external systems can interpret it.
Schema is an output layer, but it’s not a substitute for a content model. A platform can publish valid Recipe structured data and still have weak internal content operations. The reverse can also happen: a company may have a sophisticated internal model but expose only a limited subset to external systems. For the external publishing layer, read Recipe Schema: The Backbone of Discoverable Food Content.
The strongest architecture treats these as connected layers. The internal model captures what the business needs. Taxonomy and metadata provide shared meaning. Transformation maps the internal model into the formats required by search engines, partners, APIs, apps, and other destinations. For an applied starting point, see Creating a Recipe Database.
Where recipe content pipelines break down
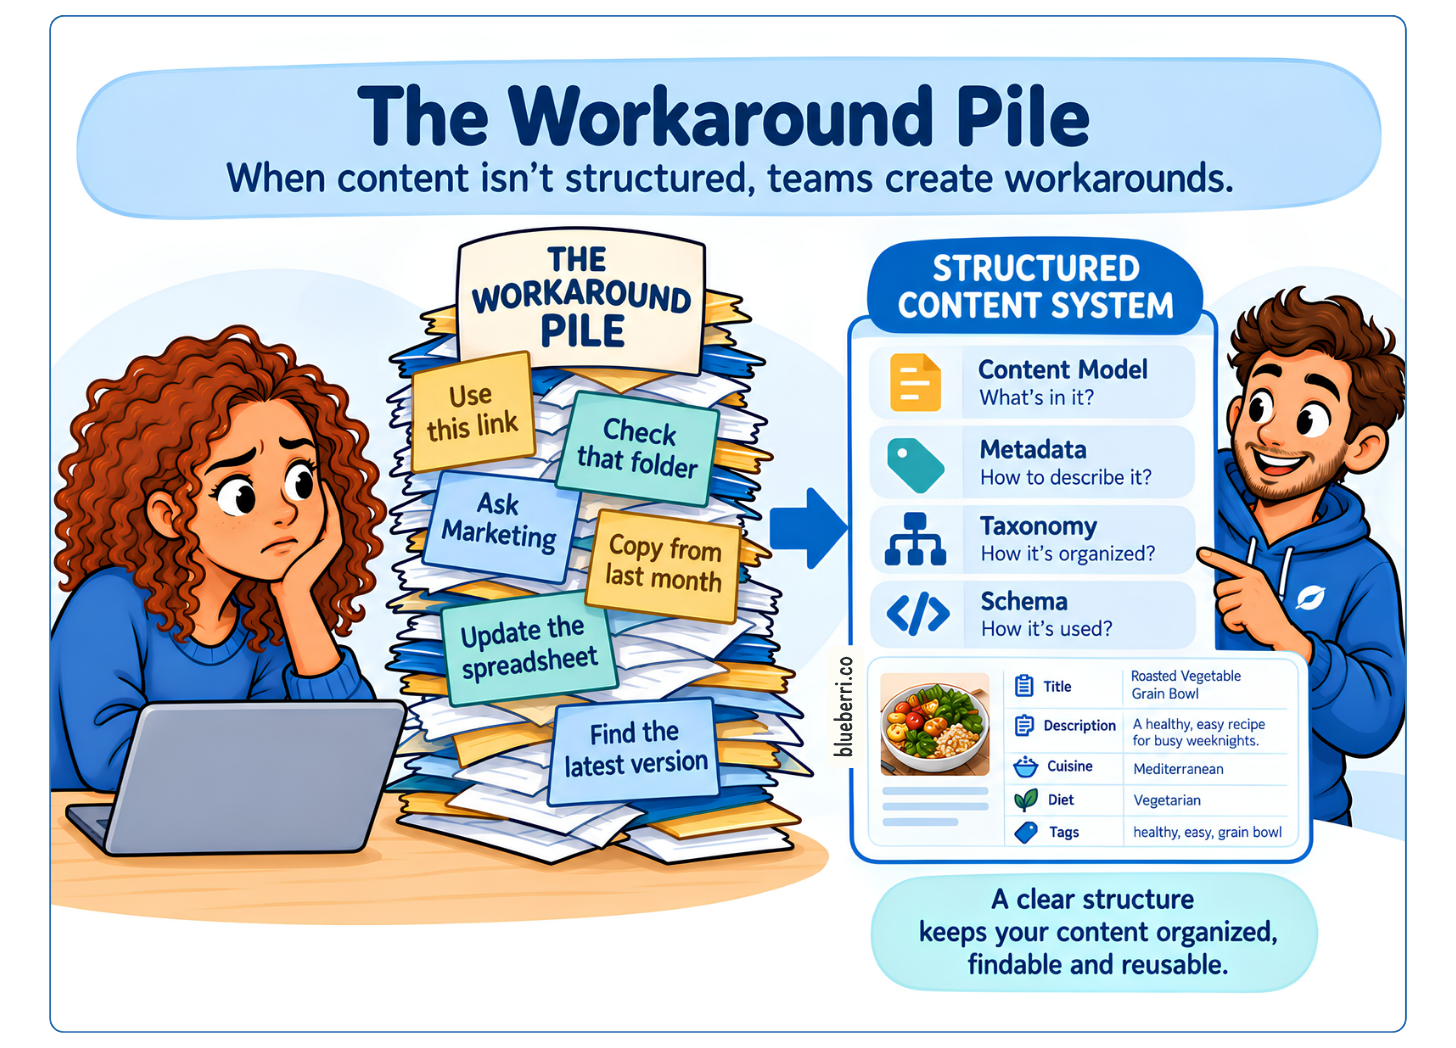
Most content problems don’t begin with a dramatic technical failure. They accumulate through small inconsistencies that seem manageable in isolation.
A partner introduces a new dietary label without a mapping. A field changes meaning but keeps the same name. A migration collapses two structured fields into one rich-text field. A team adds tags to solve a short-term discovery problem, then another team creates a second set of tags for a similar purpose. Ingredient data is cleaned manually for one integration, but the correction isn’t written back to the source system.
Over time, these workarounds become invisible infrastructure. Then the company tries to add semantic search, personalized meal planning, creator onboarding automation, licensing, or an AI cooking assistant and discovers that the content can’t support the feature without another cleanup project.
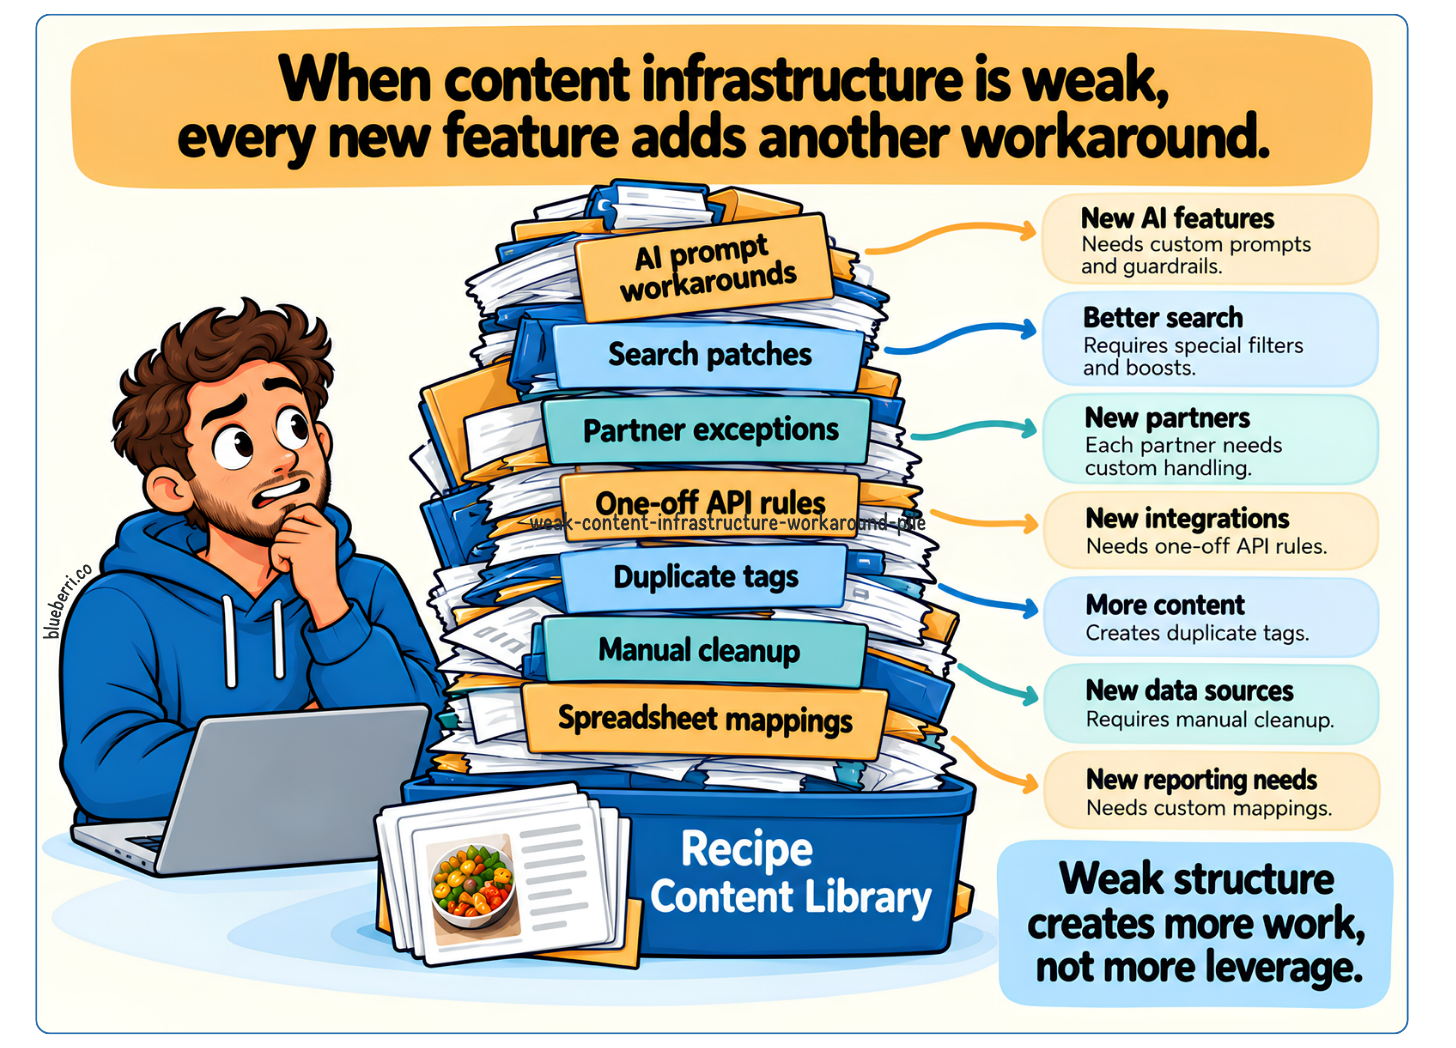
Common warning signs include duplicate or overlapping taxonomies, high volumes of manual mapping, fields with unclear ownership, inconsistent values across partners, product features that depend on spreadsheets outside the CMS, frequent exceptions in APIs, and teams that can’t explain which system is the source of truth.
Why AI makes content structure more important, not less
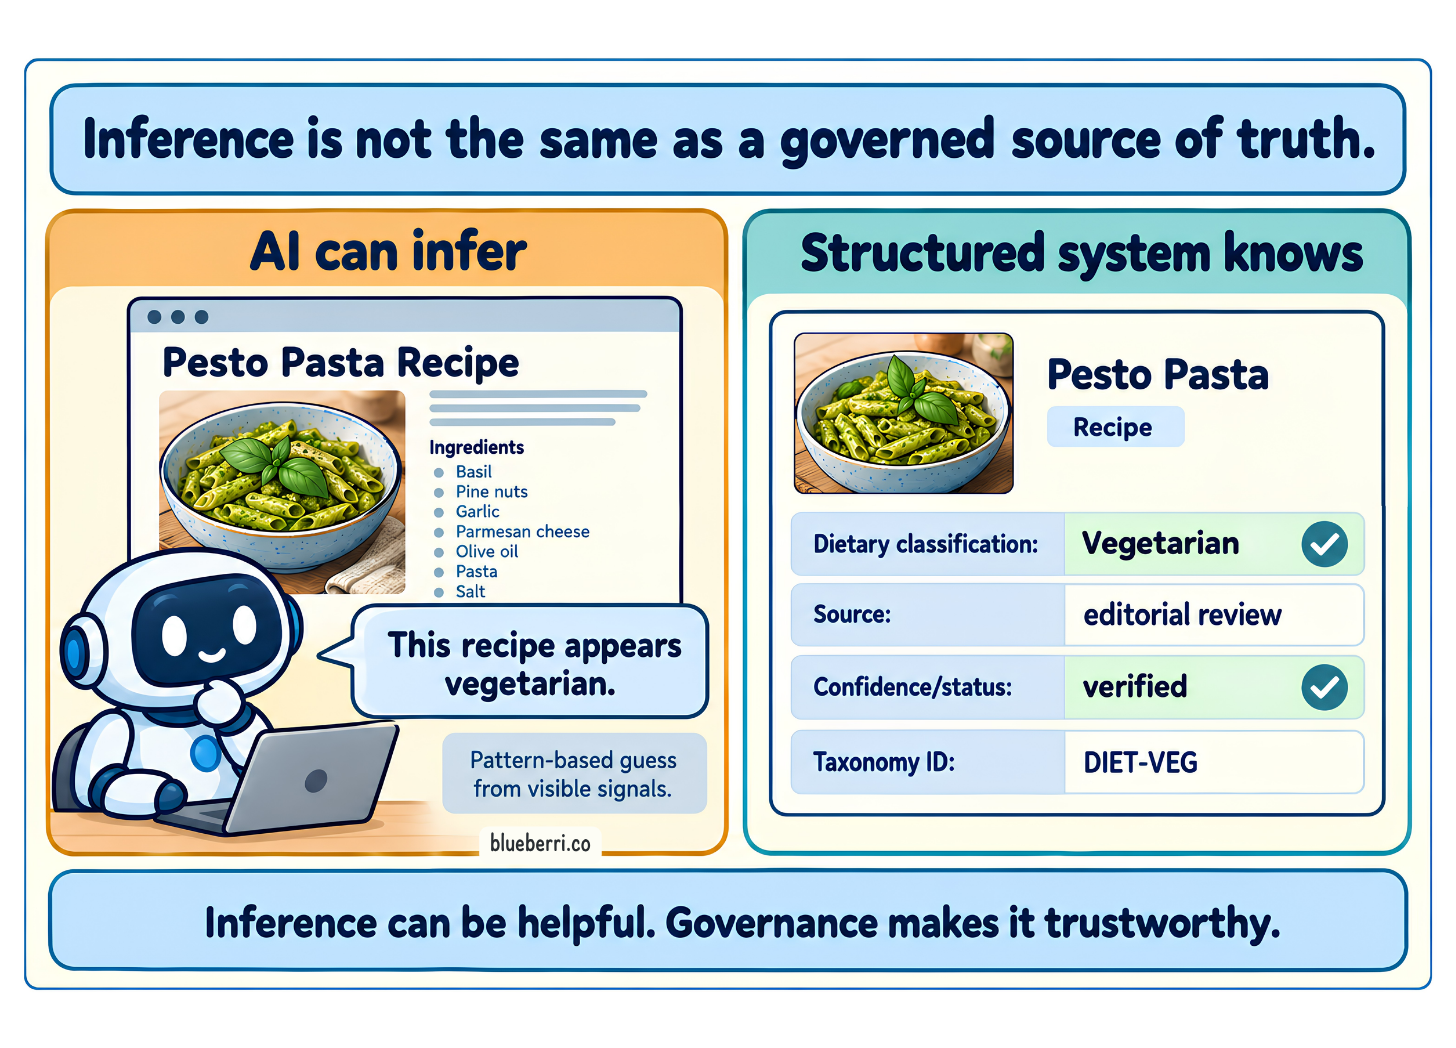
AI can make it tempting to believe structure is becoming optional. If a model can read natural language, why spend time defining fields, taxonomies, and metadata? Because language models can infer, but inference isn’t the same as a governed source of truth.
A platform may be able to infer that a recipe is probably vegetarian, but the business still needs to decide whether inferred dietary labels can be shown to users, used in filters, or relied on for personalization. An AI system may extract “one cup of milk” from a sentence, but commerce workflows still need a stable ingredient identity and rules for how that ingredient maps to products.
In Blueberri’s 2025 survey of 29 food creators, 97% said they use recipe plugins or schema markup, but only 14% felt prepared for how AI, voice assistants, and platform shifts will affect recipe discovery. Another 55% were unsure, and 31% said they weren’t prepared.
Structured source content gives AI systems better retrieval targets, clearer context, more consistent entities, and fewer ambiguous relationships. It also gives teams a place to store verified information separately from generated or inferred information.
This matters for both generative experiences and traditional search. AI doesn’t remove the need for content architecture. It raises the cost of getting that architecture wrong because weak source content can now propagate into more experiences, faster. Related reading: Generative Engine Optimization for Food Creators.
How SEO, AEO, and GEO depend on the same content foundation
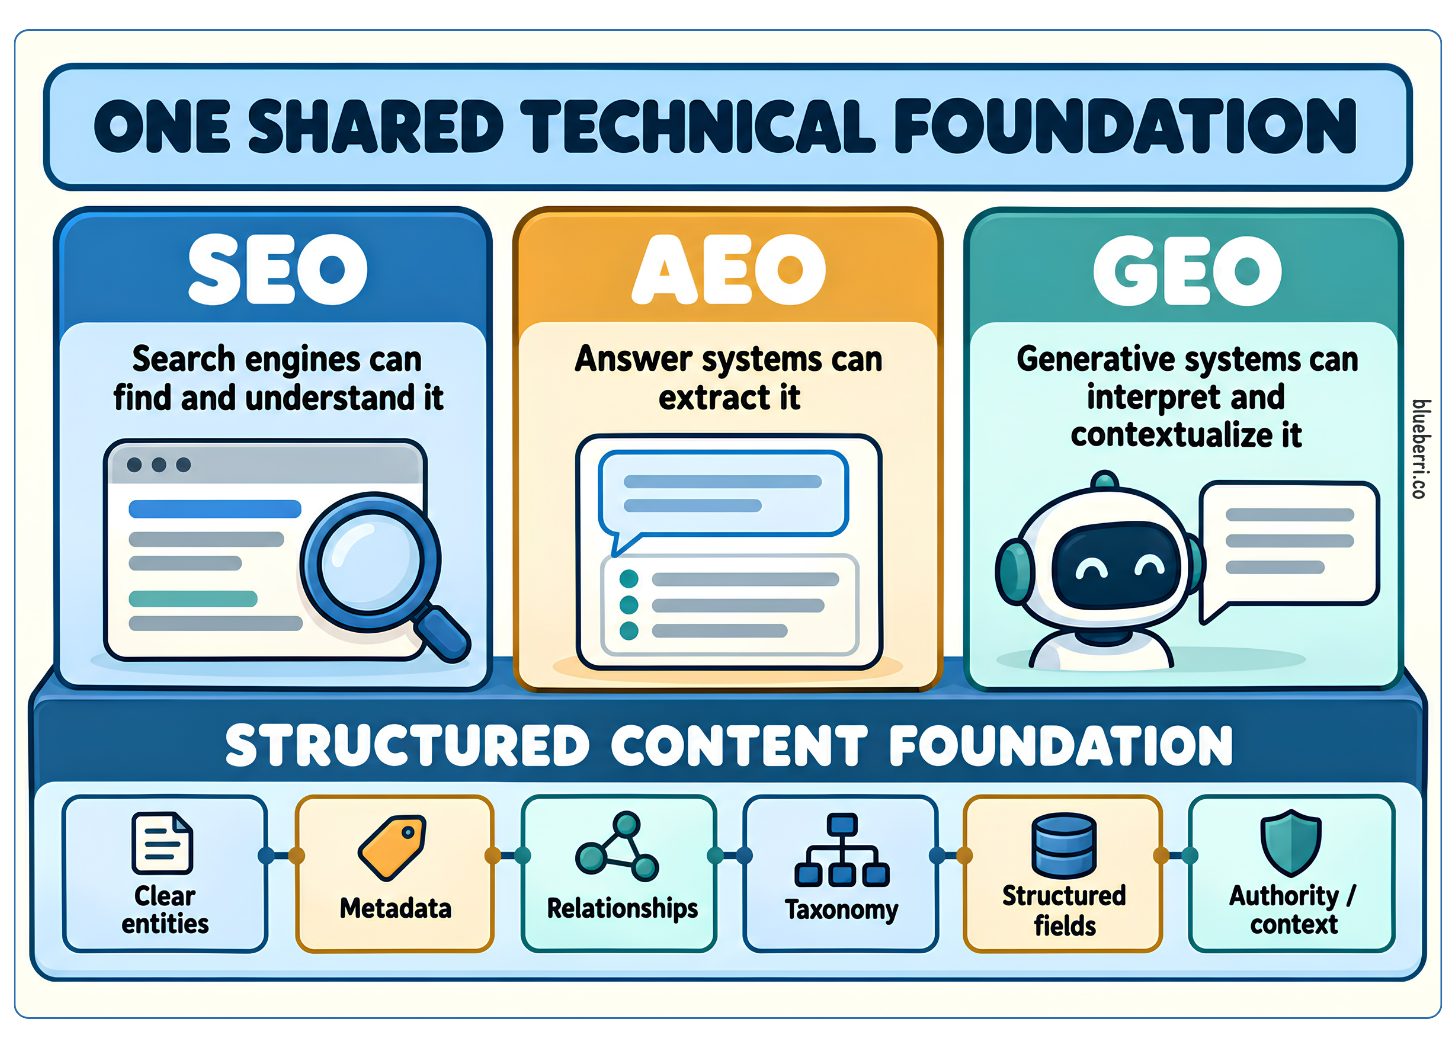
SEO, answer engine optimization, and generative engine optimization are often discussed as separate strategies. For a recipe platform, they share a common dependency: content that machines can identify, interpret, and retrieve with confidence.
SEO benefits when pages have clear topics, descriptive headings, relevant internal relationships, accurate structured data, and content that matches the user’s intent. AEO benefits when information is expressed in direct, extractable answers with explicit definitions and clear entities. GEO benefits when content provides enough context, specificity, authority, and structure for generative systems to understand what the content is about and how concepts relate.
The implementation details differ, but the source problem is similar. If a platform can’t consistently identify ingredients, techniques, cuisine, dietary attributes, recipe relationships, authorship, or source information internally, it’s harder to expose those signals externally in a reliable way.
So optimization should begin before the page template. Search and AI visibility are downstream outcomes of content architecture, not decorations added after publishing.
What product, content, and engineering teams need to decide together
Recipe infrastructure works best when it’s treated as a cross-functional product capability. Content teams understand editorial intent and quality. Product teams understand user needs and feature requirements. Engineering understands system constraints and implementation. Data teams understand measurement and relationships. Partnerships teams understand what content arrives from external sources and what partners expect in return.
The important decisions sit between those functions: Which fields are required? Which values are controlled? Who can introduce a new taxonomy term? Which system owns the canonical record? How are creator updates synchronized? Which transformations are allowed? What happens when a partner sends an unsupported value? Which fields are verified, inferred, generated, or user-entered?
When those decisions are left implicit, the system eventually encodes conflicting assumptions. When they are made explicitly, the content model becomes a shared contract between teams.
How to audit a recipe content pipeline
A useful audit starts with one representative recipe and follows it from source to destination. Don’t begin by reviewing every field in the CMS. Begin with the path the content actually takes.
Start by identifying the source. Where did the recipe come from, and what information arrived with it? Next, trace ingestion and normalization. Which values are changed, and where are those rules documented? Then inspect the internal model. Which fields are structured, which are free text, and which relationships exist between recipes, ingredients, authors, collections, and taxonomy terms?
After that, examine validation. What makes a recipe eligible for search, recommendations, commerce, or another feature? Then trace transformation and distribution. Which systems receive the content, and how is the internal model mapped to each destination? Finally, review governance. Who owns the rules when something changes?
The result should reveal both technical gaps and operational gaps. A field may exist technically but still be unusable because no one owns its definition. A taxonomy may look organized but still fail if partner data is not mapped consistently. A pipeline audit is valuable because it connects those issues to real product consequences.
Frequently asked questions about recipe content platforms
What is a recipe content platform?
A recipe content platform is a system that stores, manages, processes, and distributes recipe information for one or more digital experiences. Depending on the business, that may include a website, app, search experience, meal planner, grocery workflow, creator program, licensing product, smart-kitchen experience, or AI interface.
Why does structured recipe content matter?
Structured recipe content separates information into defined fields and relationships so software systems can use it consistently. That makes it easier to search, filter, personalize, transform, integrate, analyze, and distribute recipes across multiple products and platforms.
Is Recipe schema enough for a recipe platform?
No. Recipe schema is useful for exposing standardized recipe information to external systems, but it doesn’t define everything a food-tech company may need internally. Product features, creator operations, commerce, licensing, analytics, and AI often require a richer internal content model, additional metadata, and governed taxonomy.
What is the difference between metadata and taxonomy?
Metadata is descriptive information attached to content. Taxonomy is the controlled system of concepts and relationships used to keep that descriptive information consistent. For example, cuisine can be a metadata field, while the approved cuisine values and their relationships belong to the taxonomy.
How does structured content help AI in food tech?
Structured content gives AI systems clearer entities, attributes, relationships, and retrieval targets. It can reduce ambiguity, improve consistency, and help teams separate verified source information from generated or inferred information. It also makes it easier to build AI features on top of content without depending entirely on free-text interpretation.
Build the content pipeline before you need the next feature
The best time to discover that your recipe content can’t support a new product is before engineering starts building it.
Food-tech teams often experience content problems as feature problems. Search is weak, recommendations are inconsistent, partner onboarding is slow, shopping integrations are brittle, or AI answers lack context. But the underlying issue is often the same. The content was stored for the experience that existed at the time, not structured for the range of experiences the business would eventually need.
A strong recipe content pipeline changes that. It gives the organization a shared model, consistent definitions, reliable quality rules, and a repeatable way to move content across platforms and adapt it to new formats. That reduces manual work, makes integrations easier to maintain, and gives product teams more room to experiment without rebuilding the library every time. For more on the underlying approach, read Why Structured Content Matters for Food Bloggers.
For food-tech companies and recipe platforms, content isn’t simply something the product displays; it’s part of the product infrastructure.
Blueberri helps food-tech teams get more out of the content they already have, whether they’re building new features, connecting platforms, or working with creators.
Blueberri conducted two exploratory surveys of food creators and bloggers in 2025. One included 29 respondents and focused on recipe discovery, content strategy, and AI readiness; the other included 36 respondents and focused on recipe-management workflows and tooling. Results describe the respondents surveyed and shouldn’t be interpreted as representative of the entire food-creator industry.
Blueberri Solutions
Your next feature shouldn't require another content cleanup.
Your recipe library should support where your platform is going, not just what it does today. Blueberri helps food-tech teams get more out of the content they already have, whether they're building new features, connecting platforms, or working with creators.
- Content architecture and strategy: Build scalable models, metadata, and taxonomy.
- Recipe platform audits: Identify content gaps, workflow friction, and integration challenges.
- Fractional content leadership: Connect content, product, and engineering teams around shared priorities.
Practical strategy. Better systems. Less workaround chaos.
